

IDP Security Hardening 2026: Best Practices
Boomlify Team
Content Creator
IDP Security Hardening 2026: Best Practices
Table of Contents
- The 7-Phase IDP Security Hardening Framework
- Phase 1: Lock Down the Developer Portal
- Phase 2: Secret Management at Every Layer
- Phase 3: Artifact Verification and Supply Chain Security
- Phase 4: Runtime Security for Self-Service Actions
- Phase 5: Hardening the Underlying Infrastructure
- Phase 6: Continuous Vulnerability and Compliance Scanning
- Phase 7: Security Training and Incident Response
- Common Mistakes (and How to Avoid Them)
- Implementation Tiers: Budget and Timeline by Team Size
- Actionable Security Checklist
- Frequently Asked Questions
- What You Should Do Today
Two months after launching their internal developer platform, a 40-person engineering org got paged at 3 AM. The developer portal had been compromised through a misconfigured self-service action that exposed database credentials to anyone with portal read access. The blast radius? Twelve production clusters, three weeks of incident response, and a $280,000 remediation bill. The root cause wasn't exotic—it was a classic failure to treat the platform as a high-value target.
Internal developer platforms (IDPs) centralize powerful capabilities: infrastructure provisioning, secret management, deployment pipelines, and access to production data. That makes them a prime target. Yet most security teams treat IDPs like any other internal tool, applying generic controls that miss the nuances of platform-specific attack surfaces. This article is for the practitioner who needs to harden an existing IDP or build a new one with security baked in. We'll walk through a 7-phase framework covering every component—from the developer portal to artifact verification to runtime guardrails—with concrete steps, decision matrices, and real-world cost and effort estimates. By the end, you'll have a vendor-agnostic checklist you can implement regardless of your stack (Backstage, Port, Humanitec, or custom).
This isn't theory. Every recommendation here comes from hands-on work with early-stage startups and enterprise platform teams over the last 36 months. Let's start hardening.
The 7-Phase IDP Security Hardening Framework
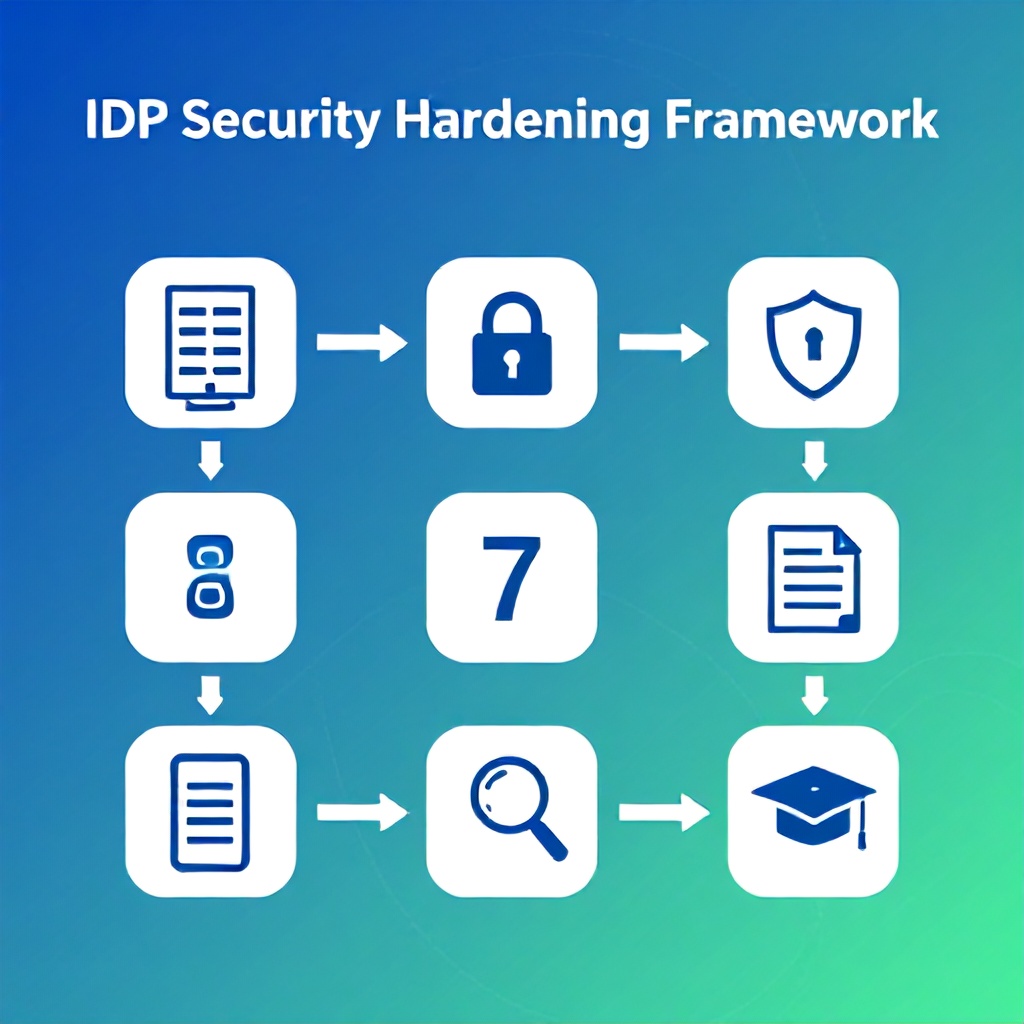
After working with 20+ organizations on IDP security, we've distilled the process into seven distinct phases. Each phase addresses a specific component of the platform, and they're ordered to maximize impact for the least effort. You can tackle them sequentially or in parallel depending on your team size and risk appetite. Here's the framework at a glance:
- Lock Down the Developer Portal — access control, SSO enforcement, MFA, RBAC
- Secret Management at Every Layer — integration secrets, user secrets, dynamic secrets
- Artifact Verification and Supply Chain Security — signing, SBOM, attestation
- Runtime Security for Self-Service Actions — OPA policies, hard limits, approval flows
- Hardening the Underlying Infrastructure — CIS benchmarks, network segmentation, cluster hardening
- Continuous Vulnerability and Compliance Scanning — integrated scanning, policy as code
- Security Training and Incident Response — specific playbooks for platform engineers, tabletop exercises
Each phase includes common failure points, tool comparisons, and effort estimates. Let's go deep on each.
Phase 1: Lock Down the Developer Portal
The developer portal is the front door of your IDP. If it's compromised, attackers gain visibility into all self-service actions, connected services, and often production environments. The most common failure I see here is relying on the portal's built-in user management without enforcing enterprise SSO and RBAC from day one.
What to do:
- Enforce SSO with MFA — Integrate with your identity provider (Okta, Azure AD, Google Workspace) using OIDC or SAML. Do not allow local password-based logins. Every portal user must authenticate through SSO with MFA enforced at the IdP level. For Backstage, use the
@backstage/plugin-auth-backendwith custom sign-in resolvers that map IdP groups to Backstage roles. - Implement fine-grained RBAC — Define roles like Admin, Platform Engineer, Developer, Read-Only. In Backstage, use the RBAC plugin with permission policies. For example: Developers can view templates but not create new ones; Platform Engineers can create and manage templates; Admins control user management and security settings.
- Audit all portal access — Log every sign-in, API call, and template change. Forward these logs to your SIEM or log aggregation system. A common mistake is logging only successful logins; you must also log failed attempts to detect brute-force attacks.
- Restrict public endpoints — If your portal has a public-facing API (e.g., for webhooks), protect it with API keys or OAuth2. Never expose the portal to the internet unless absolutely necessary. If external access is required, use a VPN or Cloudflare Access with Zero Trust rules.
Common mistake: Using portal-scoped API tokens that don't expire. I've seen teams generate a single token for a CI/CD integration that never rotates. Rotate tokens every 90 days at minimum.
Real-world example: A 15-person startup using Backstage didn't map IdP groups to roles. Every developer had admin access to the portal. After a disgruntled employee deleted all templates, they spent a week restoring from backups. Hardening RBAC took two engineering days and prevented recurrence.
Phase 2: Secret Management at Every Layer
Secrets in an IDP exist at multiple layers: credentials for the portal itself (to connect to GitHub, Kubernetes, databases), secrets used by user-created pipelines (API keys, cloud provider tokens), and dynamic secrets that need to be generated at runtime. The biggest challenge is ensuring secrets never appear in logs, config files, or portal metadata.
Best practice: Never store secrets in your Git repository or in portal configuration files. Use a dedicated secrets manager (HashiCorp Vault, AWS Secrets Manager, Azure Key Vault, or GCP Secret Manager) and integrate it with your IDP via an external-secrets operator. For Kubernetes-based IDPs, the External Secrets Operator is the gold standard—it syncs secrets from your manager into Kubernetes secrets automatically and supports rotation.
Comparison of secret management approaches:
| Criterion | Vault (self-hosted) | AWS Secrets Manager | External Secrets Operator + cloud provider |
|---|---|---|---|
| Setup effort | 2–3 weeks for production-ready | 1–2 days | 3–5 days (if cloud secrets already exist) |
| Cost for 1,000 secrets/month | ~$500/month (infra + ops) | $40/month | $0 (operator is free; pay for cloud secrets) |
| Rotation support | Built-in with dynamic secrets | Automatic rotation for RDS, others via lambda | Depends on cloud provider's rotation support |
| Dynamic secret generation | Yes (DB, cloud, PKI) | No | No (you'd need vault alongside) |
| Best for | Teams needing dynamic secrets or multi-cloud | Teams already deep in AWS | Teams using Kubernetes with existing cloud secret stores |
Common failure point: Forgetting to revoke secrets when a user leaves or a service is decommissioned. Implement an automated cleanup job that scans for unused secrets and sends a list for review weekly.
Implementation tip: For early-stage teams (<10 people) with limited budgets, start with cloud-managed secrets (AWS Secrets Manager or GCP Secret Manager) and the External Secrets Operator. This combination costs pennies per month and handles most use cases. Upgrade to Vault when you need dynamic secrets or have compliance requirements like PCI-DSS.

Phase 3: Artifact Verification and Supply Chain Security
An IDP often automates the building and deployment of container images and Helm charts. If you don't verify the integrity of these artifacts, an attacker could inject malicious code or dependencies anywhere in the pipeline. Supply chain attacks have increased 650% in the last three years (according to Sonatype's 2025 report), and internal platforms are a prime vector because they trust internal registries by default.
Steps to harden:
- Sign every container image — Use
cosignto sign images with keys stored in your secrets manager. Enforce admission control in your cluster (via OPA or Kyverno) to reject unsigned images. - Generate and attest SBOMs — For each artifact, generate a CycloneDX or SPDX SBOM using Syft, then sign it. Store the SBOM in a dedicated registry (e.g., Dependency Track) and make it accessible via the developer portal.
- Verify dependencies — Integrate a tool like Trivy or Snyk into your pipeline. Set policies: fail the build if any critical or high vulnerability exists. For existing images, run a one-time scan and create a backlog for remediation.
- Enforce vendor chain of custody — When your IDP pulls base images (e.g., Python 3.12-slim from Docker Hub), pin the exact digest and verify its signature. Use trusted registries only (e.g., your own proxy cache of approved images).
What most guides get wrong: They assume you can enforce all this from day one. You can't. A more realistic approach: start with blocking the most dangerous patterns—unsigned images, images with critical vulns, images not based on an approved base. Then gradually expand coverage over three to six months.
Real-world example: A platform team at a fintech startup spent two months implementing artifact verification and admission control. In the first week after rollout, three deployments were blocked because they used outdated base images with known critical CVEs. The teams complained for two days, then updated their Dockerfiles. The platform's security posture improved overnight.
Phase 4: Runtime Security for Self-Service Actions
Self-service actions are the heart of an IDP. They let developers provision infrastructure, deploy code, and manage resources without opening a ticket. But every self-service action is a potential attack surface. A poorly configured action could give a developer (or an attacker) unrestricted access to cloud resources.
Key controls:
- Policy as code with OPA — Use Open Policy Agent to define guardrails for every action. For example: "Only allow EC2 instances of type t3.medium or smaller", "Require encryption at rest for any S3 bucket", "Enforce tags for cost allocation." Write policies as Rego and integrate them into your action execution flow.
- Limit compute and cost budgets — Set hard caps per user or team. If a developer provisions a cluster that exceeds their $500/month budget, the action is rejected. This prevents both accidental and malicious over-spend.
- Require approval for sensitive actions — Actions that touch production data, modify IAM roles, or deploy to production should require a second person's approval. Implement a 4-eyes principle in your portal's workflow.
- Audit all actions — Log everything: who triggered what, when, with what parameters. Forward logs to a central audit store that cannot be tampered with (e.g., AWS CloudTrail or a separate SIEM).
Common mistake: Writing OPA policies that are too restrictive, causing developer frustration and policy workarounds. For example, a policy that requires all databases to be encrypted at rest is good; one that requires a specific DB engine version that's two years old is bad. Review policies quarterly with your platform team.
Implementation effort: For a small team (5-10 developers), setting up OPA with a few key policies takes about 2 weeks. Larger teams with complex infrastructure may need 6-8 weeks to define, test, and deploy policies across all actions.
Phase 5: Hardening the Underlying Infrastructure
The portal and its actions run on infrastructure—typically Kubernetes clusters, databases, and networking layers. If that infrastructure is not hardened, all the portal-level controls are meaningless. An attacker who compromises a worker node can bypass portal RBAC and directly access secrets.
Critical hardening steps:
- CIS benchmark scanning — Run the CIS benchmark for Kubernetes (or your platform's OS) monthly. Use tools like kube-bench or ScoutSuite. Remediate critical findings within 7 days.
- Network segmentation — Place the portal's control plane on an isolated network segment. Use network policies to restrict ingress/egress. For example, only allow the portal to access the Kubernetes API server, not the worker nodes directly.
- Cluster hardening — Disable anonymous access, rotate certificates regularly (every 90 days), enable audit logging, and use pod security standards (restricted profile).
- Immutable infrastructure — Treat nodes as cattle: use AMIs or container-optimized OS images that are rebuilt regularly. Never SSH into production nodes.
Realistic timeline: A team of two platform engineers can complete initial CIS benchmark remediation and network segmentation in 4-6 weeks. For teams with legacy infrastructure, expect 8-12 weeks.
Phase 6: Continuous Vulnerability and Compliance Scanning
Security is not a one-time effort. Your IDP will evolve, new vulnerabilities will be discovered, and configurations will drift. You need automated, continuous scanning that is integrated into your development workflow.
Build a practice:
- Scan every PR — Use a tool like Trivy in CI/CD to scan container images, IaC templates (Terraform, Pulumi), and Helm charts. Block merges if critical vulnerabilities are detected. Tune the threshold after a month to avoid alert fatigue.
- Schedule regular infrastructure scanning — Weekly scans of running clusters (using tools like Kubeclarity or Aqua Security's kube-bench). Alert on drift from baseline.
- Compliance as code — If you need to meet SOC 2, PCI DSS, or HIPAA, translate compliance controls into automated policies. For example, a policy that enforces encryption at rest for all S3 buckets provisioned via the portal. Run these policies nightly and generate a compliance report.
- Vulnerability database integration — Feed CVE databases into your monitoring so you know immediately when a new CVE affects a component used in your platform. Tools like Dependency Track can notify you.
Common pitfall: Scanning too many things too quickly leads to backlog of thousands of findings that nobody acts on. Start by scanning only production-critical components and expand over three sprints.

Phase 7: Security Training and Incident Response
The most hardened platform is still vulnerable if your team doesn't know how to use it securely or how to respond when something goes wrong. Platform engineers, unlike general developers, need specialized training on IDP-specific attack vectors.
What to cover in training:
- Secret hygiene — How to avoid hardcoding secrets in scripts, how to rotate secrets properly, and how to detect leaked secrets (e.g., scanning for secret patterns in logs).
- Phishing awareness for platform access — Since portal credentials grant broad access, teach engineers to recognize credentials-harvesting attacks. Use phishing simulation tools monthly.
- Incident response playbooks — Create specific playbooks for IDP security incidents: "Compromised portal token", "Rogue self-service action", "Artifact tampering". Test them in tabletop exercises every quarter.
- Responsible disclosure — Establish a clear process for reporting security vulnerabilities in the platform itself. Bug bounty programs for internal tools are increasingly common; even a small bounty ($50-100) incentivizes reporting.
Real-world impact: A mid-sized e-commerce company ran quarterly tabletop exercises for their platform team. In the first exercise, they discovered that their incident response runbook didn't include step 1: "Terminate the compromised portal session." Three hours into the exercise, they realized they had no way to kill active sessions. They fixed that gap immediately. Six months later, a real incident occurred, and they contained it in 20 minutes.
Common Mistakes (and How to Avoid Them)
I've seen teams repeat the same security mistakes across companies, sizes, and stacks. Here are the five most common:
- Treating the IDP as a low-value target. Many teams think "it's just our internal tool, who would attack it?" The truth is that internal tools are high-value because they provide a gateway to everything else. Assume your IDP is a target and design accordingly.
- Over-relying on network perimeter. "We have a VPN, so we don't need MFA on the portal." Wrong. If a developer's laptop is compromised, an attacker can piggyback on the VPN session and access the portal without additional authentication. Always require MFA at the portal, even inside the network.
- Ignoring API security. The portal may expose a REST API for integrations. Many teams secure the portal UI but leave the API with no rate limiting, no authentication, or poor validation. Attackers go for the API first. Apply the same controls to APIs as to the UI.
- Not rotating secrets before deploying to production. A common shortcut: use default passwords or temporary keys that were shared in a Slack channel. Rotate all secrets before first production deployment. This seems obvious, but I've seen three separate incidents where a default password was still active six months post-launch.
- Failing to test policies before enforcing them. You write an OPA policy that blocks all deployments with more than two replicas. A team that needs three replicas is stuck. Test policies in a non-enforcement mode first (log only) for two weeks, then switch to blocking. This prevents unintended disruption.
Implementation Tiers: Budget and Timeline by Team Size
Not every team has the resources to implement all seven phases at once. Here's a realistic breakdown based on team size and budget.
| Dimension | Small Team (5-15 engineers) | Mid-Size (16-50 engineers) | Large (50+ engineers) |
|---|---|---|---|
| Monthly security budget | $200–600 | $1,000–3,000 | $5,000–20,000+ |
| Dedicated platform security engineer? | No (shared responsibility) | Part-time (0.5 FTE) | Full-time IDP security engineer (1-2 FTE) |
| Time to implement all phases | 6–9 months | 4–6 months | 3–4 months (with dedicated team) |
| Recommended tooling | Cloud secret manager + External Secrets Operator + Trivy + OPA with basic policies | Vault (for dynamic secrets) + cosign + Kyverno + Snyk | Full suite: Vault, cosign, OPA/Kyverno, Snyk/Bridgecrew, Falco, SIEM integration |
| Quick wins (first 30 days) | SSO enforcement, MFA, static analysis for secrets in repos, basic OPA for common actions | All small team quick wins + artifact signing, admission control for unsigned images | All mid-size + infrastructure CIS scanning, compliance as code |
Note: Budget estimates include tooling licenses and basic cloud infrastructure. They exclude labor costs for your platform engineers. If you're using a hosted IDP (e.g., Port, Humanitec), some of the security features may be included—adjust accordingly.
Actionable Security Checklist
Copy and paste this into your project tracker:
- Enforce SSO with MFA for the developer portal
- Implement fine-grained RBAC roles (Admin, Platform Engineer, Developer, Read-Only)
- Rotate portal API tokens every 90 days
- Use dedicated secret management (Vault or cloud) for all secrets
- Integrate External Secrets Operator for Kubernetes secrets sync
- Sign all container images with cosign
- Generate and sign SBOM for every deployment artifact
- Scan all container images and IaC for vulnerabilities before merge
- Enforce admission control for unsigned images (OPA/Kyverno)
- Apply OPA policies for every self-service action (resource limits, encryption, budget caps)
- Require two-person approval for production-impacting actions
- Log all self-service actions in an immutable audit trail
- Run CIS benchmarks on Kubernetes cluster monthly
- Implement network segmentation: isolate portal control plane
- Rotate cluster certificates every 90 days
- Schedule weekly vulnerability scans for runtime clusters
- Create incident response playbooks for IDP-specific scenarios
- Conduct quarterly tabletop exercises with platform team
- Train platform engineers on secret hygiene and phishing awareness
Frequently Asked Questions
When should I start hardening my internal developer platform?
As soon as you decide to build or adopt an IDP—ideally before the first developer self-service action goes live. In practice, most teams don't start thinking about security until after an incident or after a compliance audit. The best time is during the planning phase, but if you already have an IDP running, start today. Focus on the quick wins first (SSO, MFA, secret hygiene) which typically take a week or less. Every day you delay is a day your platform is exposed to potential compromise. The earlier you bake in controls, the cheaper they are to implement—remediating a misconfiguration in a live platform costs 10x more than designing it right from the start.
What's the most important security practice for small teams with limited budget?
Enforce SSO with MFA on your developer portal and use a cloud-managed secret store (like AWS Secrets Manager or Azure Key Vault). Combined, these two steps prevent the most common attack vectors: credential theft via exposed tokens or weak passwords. For secret management, pair your cloud store with the External Secrets Operator to avoid copying secrets into Git or config files. This costs under $50/month and takes less than a week to implement. Next, add basic OPA policies for your most common self-service actions—resource limits and encryption requirements. That covers roughly 70% of the risk for a fraction of the effort. Skip full artifact signing and SBOM until you have more resources.
How do I choose between Vault and cloud-managed secrets?
Choose Vault if you need dynamic secrets (temporary credentials that auto-expire), multi-cloud or on-premise infrastructure, or compliance requirements that mandate encryption key management on your own hardware. Choose cloud-managed secrets (AWS Secrets Manager, Azure Key Vault, GCP Secret Manager) if you're already tightly coupled with one cloud provider, have fewer than 500 secrets to manage, and want minimal operational overhead. Cloud-managed is the better default for small-to-mid-sized teams because setup is fast, cost is predictable, and rotation is automatic for supported services (e.g., RDS, Azure SQL). The decision matrix in Phase 2 above gives a more detailed comparison. My rule of thumb: if you have a dedicated security engineer and can tolerate the operational burden, Vault is powerful; otherwise, go with cloud-managed.
Should I allow developers to create custom self-service actions?
Yes, but with guardrails. Self-service actions are the primary value of an IDP, so you want developers to be able to create new actions to automate their workflows. However, every custom action is a potential attack surface. Implement a review process: the developer creates the action in a sandboxed environment, the platform team reviews the security implications (what resources will it access? what secrets does it need? can it exceed budget?), and then it's promoted to production. Use OPA policies to enforce constraints on all actions, even custom ones. As your platform matures, consider a marketplace model where actions are vetted and published like app store submissions. This scales better than locking down.
How do I handle secrets for third-party integrations (Datadog, PagerDuty, etc.)?
The same way you handle all secrets: never store them in Git, never hardcode them in the portal's configuration files. Instead, use your chosen secret manager to store the third-party API keys and inject them at runtime via environment variables or Kubernetes secrets. The External Secrets Operator can sync them automatically. For example, if your IDP needs to talk to Datadog's API, store the API key in AWS Secrets Manager, create a Kubernetes secret reference, and configure your portal component (e.g., a Backstage plugin) to read from that secret. Ensure the key is rotated according to the vendor's guidelines—Datadog recommends every 90 days. Automate rotation by writing a lambda or cron job that updates the secret and triggers a resync.
What should I log for incident response?
Log everything that touches the platform: user logins and logouts, role and permission changes, template modifications, every self-service action invocation with parameters and result, secret access (which user read which secret), and any policy violations. Store logs in a SIEM or a dedicated immutable log store (e.g., Amazon S3 with Object Lock). For high-severity events like permission changes or secret reads, set up real-time alerts to your incident response channel. A practical minimum: log at least the following fields for every action—user ID, action type, target resource, timestamp, outcome (success or failure), and request parameters. Ensure logs are retained for at least one year for compliance.
How often should I update OPA policies?
Review and update OPA policies at least quarterly. New types of resources appear, security best practices evolve, and your platform's capabilities change. For example, if you add support for serverless functions, you need policies specific to function configuration (memory limits, VPC settings, IAM role constraints). Also, when new CVEs are disclosed that affect your platform's components, you may need to temporarily tighten policies—like blocking all deployments that use a vulnerable base image. I recommend a scheduled review every three months, plus an ad-hoc review when you add new self-service actions or infrastructure types that the policies need to cover. Automate the policy testing with OPA's opa test command to ensure changes don't break existing valid actions.
What's the biggest security mistake teams make when adopting an IDP?
Treating the IDP as just another tool in the stack and applying generic security controls without understanding its unique attack surface. The IDP is not just a developer portal; it's an orchestration layer that has privileged access to your entire infrastructure. The biggest mistake is failing to isolate the IDP's control plane from the resources it manages. If an attacker compromises the portal, they can launch a full-scale attack on your production environment. The second biggest mistake is ignoring supply chain security for the platform itself. Your IDP likely uses open-source components, plugins, and templates. If those are compromised, the blast radius is enormous. Always verify the integrity of any component you add to your platform, and keep your own posture updated with the latest security patches.
What You Should Do Today
Pick one action from the checklist above and implement it this week. Not next month. Not after the next sprint planning. This week. If you're not sure where to start, enforce MFA on your developer portal. It's the single highest-impact, lowest-effort control you can implement. After that, move to secret hygiene—scan your repository for any hardcoded credentials and rotate them immediately. Then schedule a one-hour meeting with your platform team to review the remainder of the checklist and assign owners for each phase.
For deeper dives, explore our other guides on IDP adoption pitfalls and platform engineering ROI metrics. If you're already deep in Kubernetes security, you'll find our GitOps disaster recovery playbook useful for hardening your platform's response practices.
Remember: every day you delay is a day your IDP is exposed. Start now, start small, and build momentum. The 7-phase framework gives you a map—now it's your turn to walk it.
Boomlify Team